Sequence modeling · Data engineering
Protogen
A small causal protein-sequence generator, with careful dataset cleanup and a reproducible experiment.
Python / PyTorch / FastAPI / React
A generation experiment starts with trustworthy data.
425 → 85rows to unique sequences
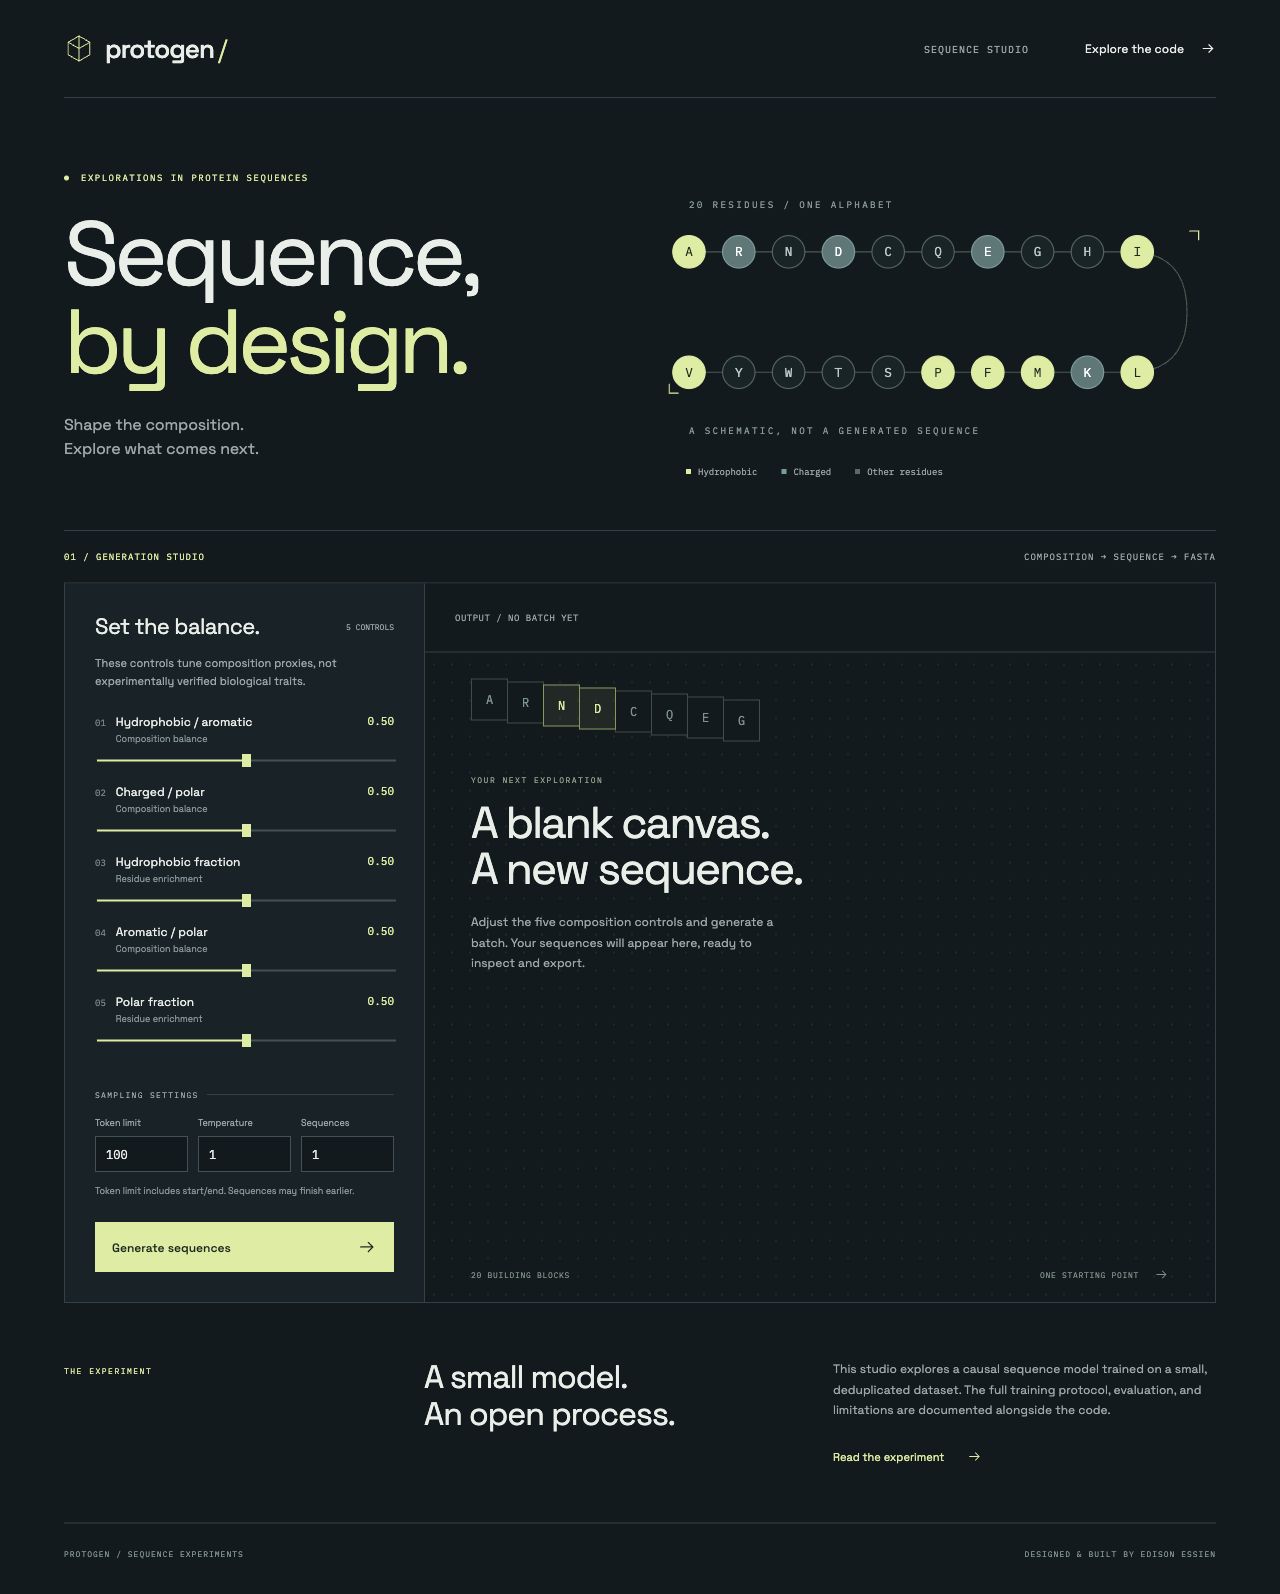
Protogen combines dataset preparation, autoregressive sequence generation and an interface for exploring composition controls. The refresh addressed repeated data and causal masking before running a small CPU experiment.
Implementation & scope
- Removed 340 duplicate rows before creating seeded training, validation and test partitions of 68 / 8 / 9 unique sequences.
- Built a 2-layer, 4-head PyTorch generator with five heuristic composition controls and FASTA export.
- Ran a three-epoch CPU experiment against a training-only unigram baseline; added 18 regression tests.
Reading the results
Composition controls are heuristics. Generated sequences have not been validated for biological function. The small experiment is not evidence of therapeutic or laboratory efficacy.
Source code & local setup ↗- 01Deduplicate
- 02Split dataset
- 03Train causally
- 04Generate sequence